



DocVortex is a standalone Python engine for parsing and converting documents. It reads native text and document structure into a unified representation, then exports the result in the formats your workflow needs.
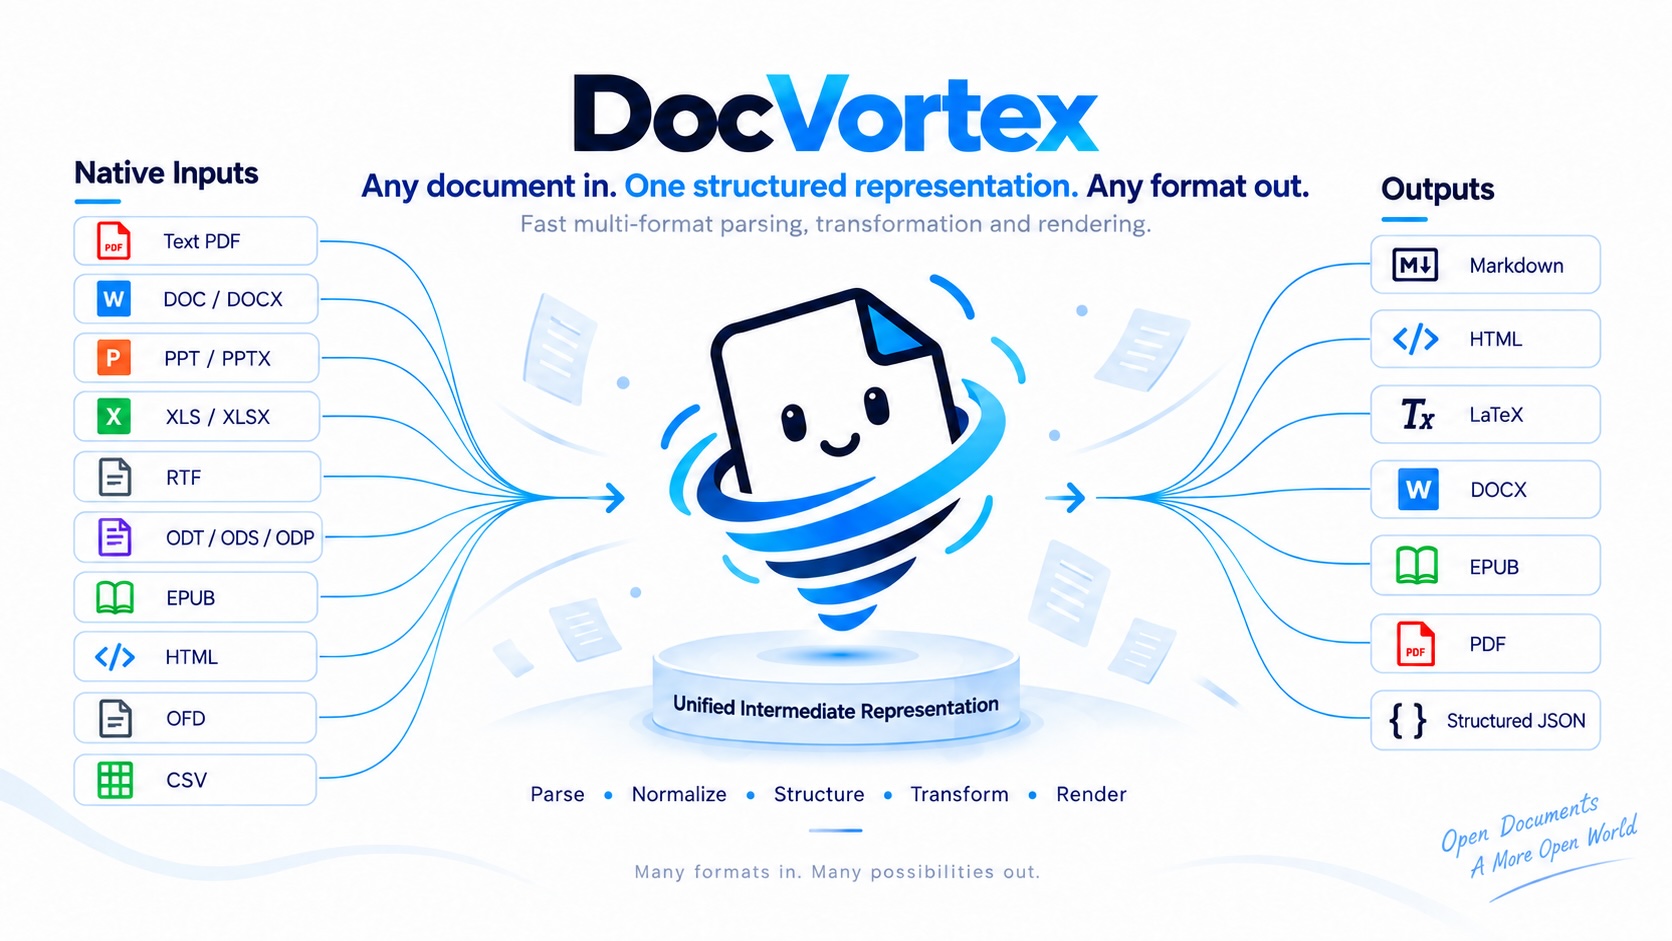
- Multi-format input — read text PDFs, Office files, OpenDocument files, EPUB, HTML, OFD, CSV and TSV.
- Parse once, export many times — reuse the same result for Markdown, HTML, LaTeX, DOCX, EPUB, PDF and structured JSON.
- Portable results — save document structure and image assets in a Bundle, then export again without the source file.
- Composable APIs — use the complete pipeline or integrate analysis, postprocessing and rendering separately.
Native parsing works without an OCR or VLM inference service. Use DocVortex directly through its CLI or Python SDK.
Requires Python 3.10–3.14.
pip install docvortexConvert a text PDF to Markdown:
docvortex convert report.pdf --format markdown --output output/report.mdReplace report.pdf with a local file in any supported input format.
Use --format to choose the output; run docvortex convert --help for options.
The root-level --log-level option controls loguru output and defaults to info.
It must precede the command; DOCVORTEX_LOG_LEVEL=warning can also configure it.
Parse a document once and export it twice:
import docvortex

result = docvortex.parse("report.pdf")
result.export("output/report.md", output_format="markdown")
result.export("output/report.docx", output_format="docx")
The result owns its document structure and assets, so further exports do not
reopen or reparse the source. Existing output files are protected by default;
use overwrite=True in Python or --overwrite in the CLI to replace them.
| Document family | Formats |
|---|---|
| PDF with native text | |
| Word & rich text | DOC, DOCX, RTF |
| Presentations | PPT, PPTX |
| Spreadsheets | XLS, XLSX, CSV, TSV |
| OpenDocument | ODT, ODS, ODP |
| E-books & web documents | EPUB, HTML |
| Open Fixed-layout Document | OFD |
| Output | --format / output_format |
|---|---|
| Markdown | markdown |
| HTML | html |
| LaTeX | latex |
| Word document | docx |
| EPUB e-book | epub |
pdf |
|
| Structured JSON | structured_content |
PPT/PPTX and XLS/XLSX are input formats only. Structured JSON is an export format; the document JSON protocol separately defines the analysis and intermediate representations.
A Bundle packages the parsed document and its image assets for reuse across processes or machines. Load it whenever you need another output format:
import docvortex

result = docvortex.parse("report.pdf")
result.save_bundle("output/report.bundle")

restored = docvortex.load_bundle("output/report.bundle")
restored.export("output/report.epub", output_format="epub")
The restored result works without the original file. See the usage guide for Bundle contents, asset handling and overwrite rules.
Need only the title, authors or other source properties?
docvortex.extract_metadata()
reads metadata without parsing the document body.
- Text PDFs: native parsing uses the document's existing text and structure. Scanned pages requiring OCR need an external OCR or inference service.
- PDF classification:
docvortex classify report.pdfreturnstxtorocr. Classification is explicit and does not start inference; parsing does not automatically switch backends. - PDF export: PDF sources with page geometry default to block layout restoration, with selectable text and HTML-based tables; charts retain region images. Other sources and older results use semantic reflow. Use
--pdf-layout original|reflowto select explicitly; fonts, line breaks and drawing instructions are not reproduced losslessly. See PDF output layout.
| Guide | What you will find |
|---|---|
| Usage | Stage APIs, PDF pages, classification, images and Bundles |
| Agent skill | CLI and Python SDK workflows for agents; copy the entire skills/docvortex folder to reuse |
| Examples | Local PDF and Office samples with a runnable demo |
| Metadata | Source properties and per-format coverage |
| JSON protocol | Document schemas, extensions and protocol migration |
| HTML protocol | Semantic markers and round trips |
| Public SDK & migration | Supported integration boundaries and the 0.4 upgrade |
| Rendering ownership | DocVortex exports and MinerU-specific renderers |
From a local checkout:
uv venv
uv pip install -e ".[test,dev]"
uv run --no-project python -m pytest -q
uv run --no-project ruff check src
uv run --no-project ruff format --check src
uv build
Bug reports and contributions are welcome. When reporting a parsing issue, include a reproducible command and a sample document you can share in GitHub Issues.
DocVortex project code is released under the MIT License.